In this post I’m going to show you just how easy it is to have local large language models, or LLM’s, also known as AI, running on your own Windows PC, for free. Basically it’s like having a local copy of ChatGPT, but you can also pick and choose from tons of different AI models such as Meta’s Llama, Google’s Gemma, and even the recently popular and controversial DeepSeek R1. But, since these large language models are running locally on your own computer, they aren’t phoning home and giving all of your data to large corporations or International governments. And you can even run uncensored models that break free from the guardrails put in place by their online versions.
This is an awesome project that takes no more than 10 to 15 minutes until you have your very own powerful ChatGPT-style local AI interface, so let’s dig in and get started!
Hardware Requirements
Large language models can run on pretty much any Windows PC, but they’re going to be much faster with a good CPU, a good GPU, or if you have one of the new CPUs that come with an embedded NPU, or Neural Processing Unit designed for AI-intensive applications such as Intel’s Lunar Lake, Qualcomm’s Snapdragon 8 Gen 1, Nvidia’s Jetson AGX Xavier, or AMD’s AMD Ryzen AI.
But, they also run just fine without a super powerful PC or a special processor. I’m going to be using a Minisforum MS-A1 which has an AMD Ryzen 7 8700G with built-in Radeon 780M graphics and 32 gigs of RAM. You can pick one of these up brand new for just over $700 bucks. The point being is that you don’t need a super powerful GPU like a 4000-series NVIDIA to run a large language model locally.
Project Overview
This project consists of 3 main components. We’re first going to install Ollama, which is an open source project that allows users to run large language models directly on their own hardware. Then we’ll be installing Docker Desktop for Windows so that we can finally run Open-WebUI which is a graphical user interface for the large language models that looks and feels very much like ChatGPT.
If you find this guide useful, consider buying me a coffee!
Prepare Windows
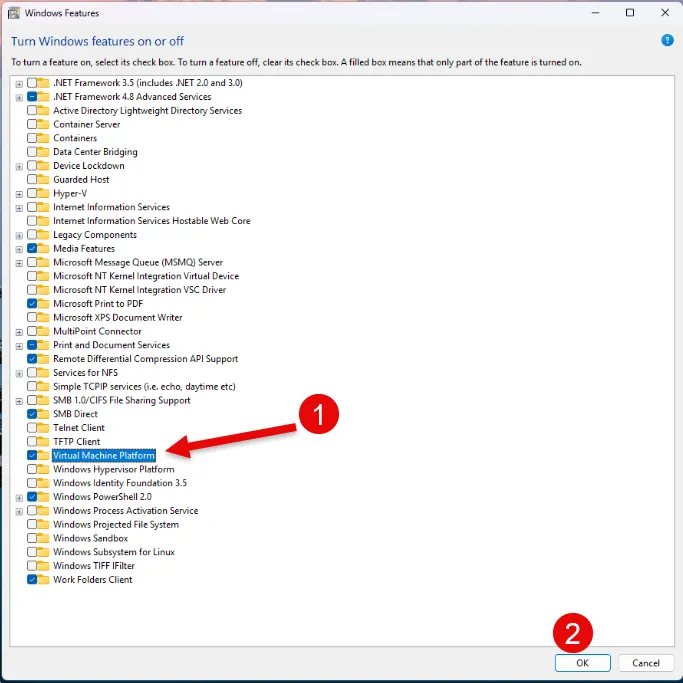
The first thing we want to do is enable a Windows Feature called Virtual Machine Platform. This installs what’s known as WSL2 or Windows Subsystem for Linux 2, and it works with Windows 11 and Windows 10 version 1903 build 18362 or higher.
To install WSL2, hit the Windows or start button and type windows features. Then scroll down until you see Virtual Machine Platform. Check the box, and click OK. This is gonna apply that feature to Windows and then ask you to reboot.
Ollama Install
Once rebooted, head over to ollama.com/download and click Download for Windows. The setup file for Ollama is about 750 megs, so it may take a while to download depending on your Internet connection. Once downloaded, run the setup for Ollama and click ‘Install.’
One thing that might throw you off about Ollama is that there’s no GUI at all. Ollama lets you run large language models in your Windows CLI, or command prompt, so you can actually start working with models immediately…but we want this to function like ChatGPT with a nice user interface that saves our previous conversations.
Docker Desktop Install
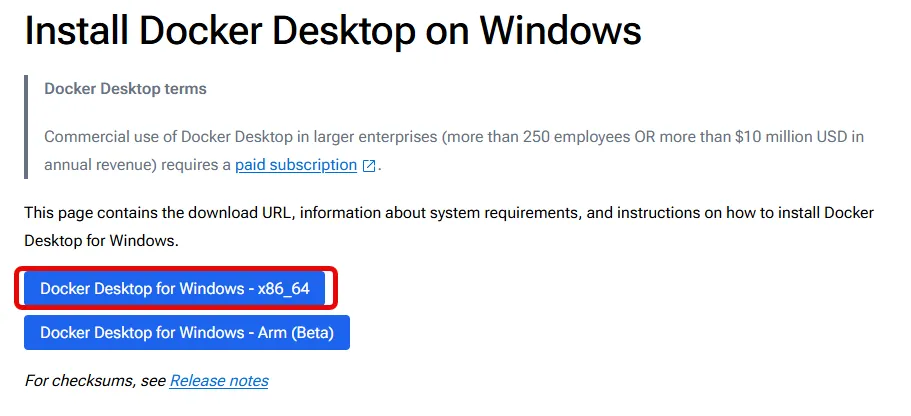
So the next thing we’re going to do is install Docker Desktop for Windows. Head on over to docs.docker.com/get-started, click on Get Started, and then click on Docker Desktop for Windows. From here you can download the x86_64 version of Docker Desktop. Once downloaded, click on the downloaded file and Docker Desktop will install onto your PC.
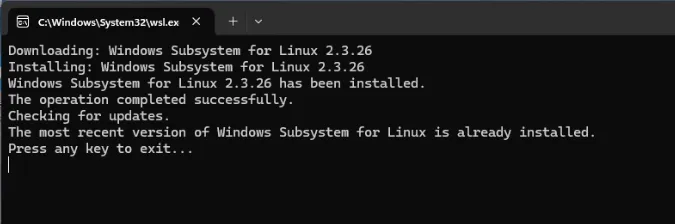
Once installed, reboot your computer and when you’re back up and running, you may get a CMD prompt pop-up telling you to press any button to update to the latest version of WSL2. Go ahead and click that.
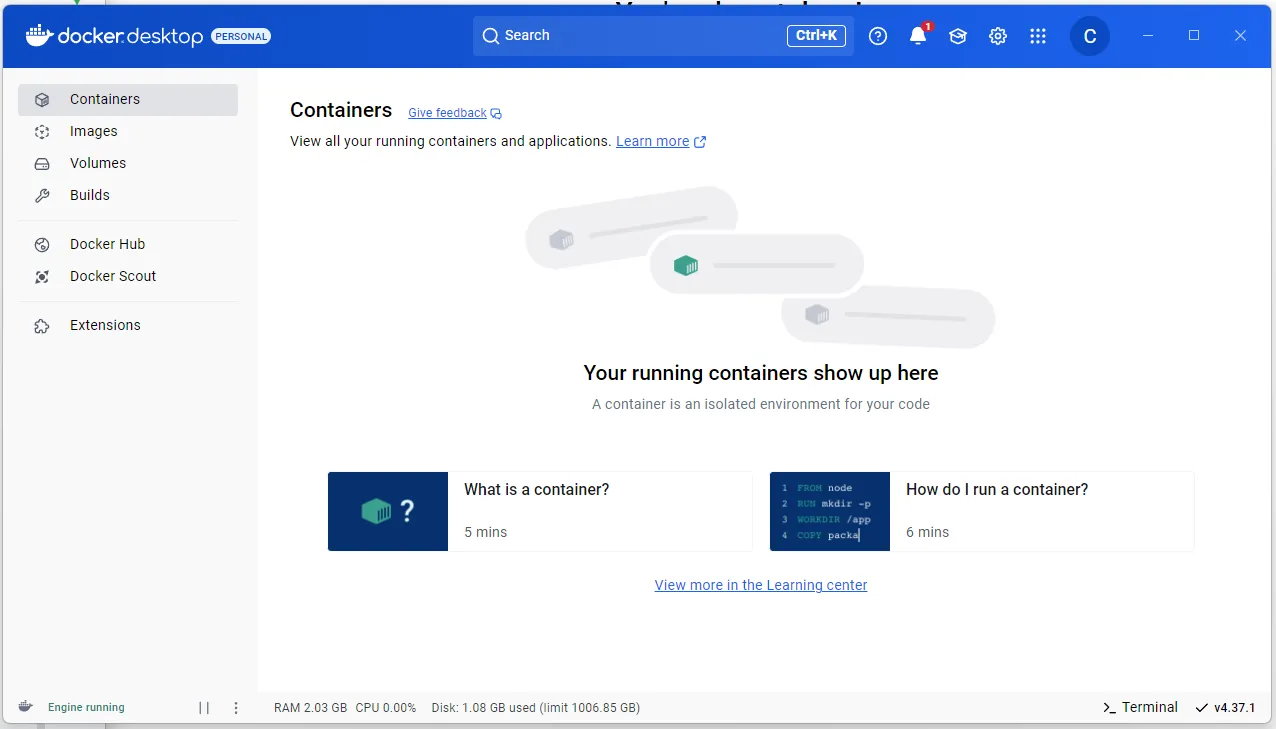
Then you can finish going through the Docker wizard and then you’ll see the Docker Desktop interface which should have no containers in it already if you’re just installing Docker Desktop for the first time.
Open-WebUI Install
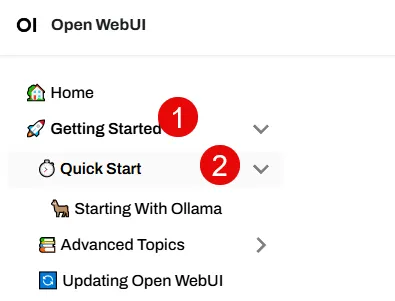
Next we’re going to install Open-WebUI which is a ChatGPT-style interface for Ollama. Open-WebUI service that runs as a container in Docker. Navigate to https://docs.openwebui.com and click ‘Getting Started’ followed by ‘Quick Start.’
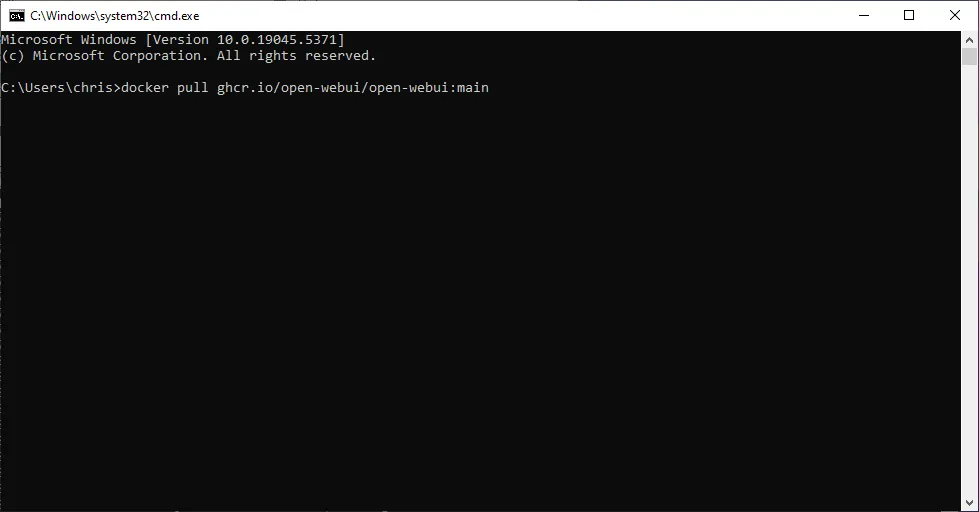
Docker is selected by default, so just copy the first command which will pull Open-WebUI down to our local machine.
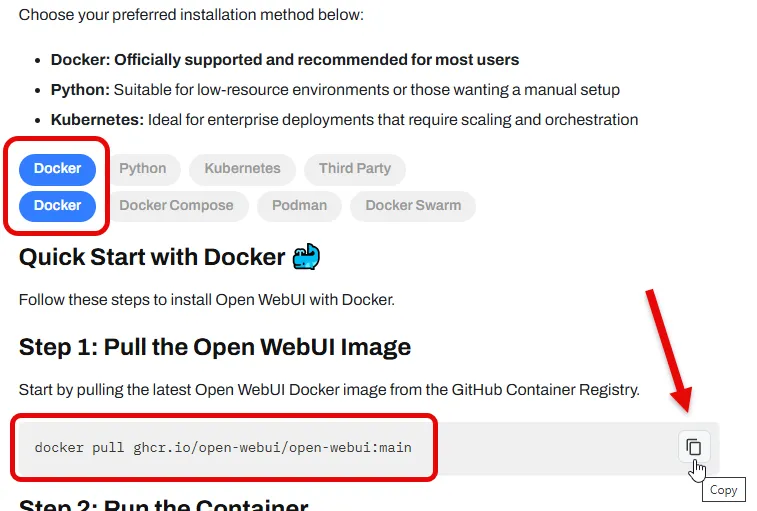
docker pull ghcr.io/open-webui/open-webui:mainHit Windows Key + R to run a new program and type CMD to open command prompt. Then paste in the first command and hit ENTER.
Next we want to run the Docker container, but first we have to take a look at the various options. For my PC, I’m just gonna grab this first command that has default settings, but if you’re running an NVIDIA GPU and you want to take advantage of the GPU processing power, then you’ll want to copy the command that has NVIDIA GPU support down below.
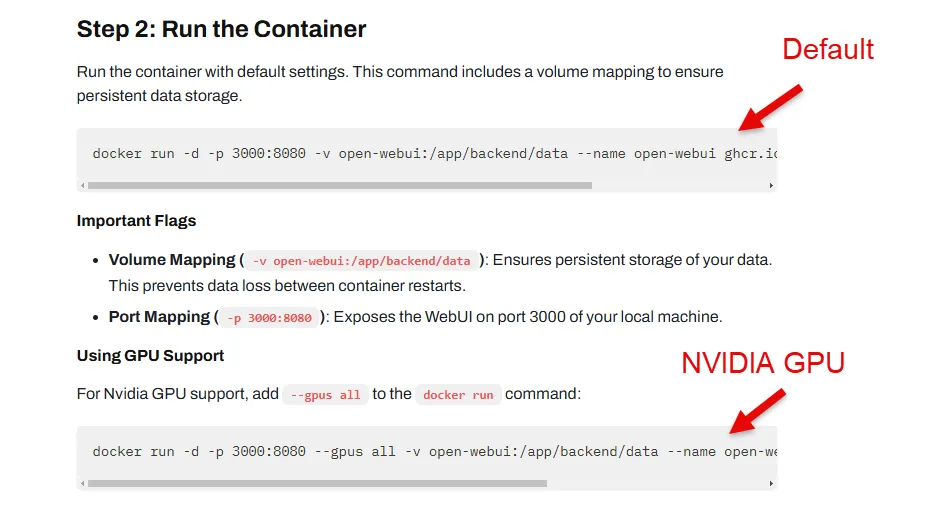
Run without NVIDIA GPU support:
docker run -d -p 3000:8080 -v open-webui:/app/backend/data --name open-webui ghcr.io/open-webui/open-webui:mainRun WITH NVIDIA GPU support:
docker run -d -p 3000:8080 --gpus all -v open-webui:/app/backend/data --name open-webui ghcr.io/open-webui/open-webui:cudaI’m going to run the container by pasting in the default settings into my CMD prompt. If you get any pop-ups warning you about the Windows Firewall, just click Allow.
If we go back to Docker Desktop, we should now see that our container is running since we have the green light. At this point, you can start and stop the Open-WebUI container at any time. I like to disable the container when I’m not actively using the LLM. Just hit the ‘STOP’ button to stop, and then the ‘PLAY’ button to start it back up.
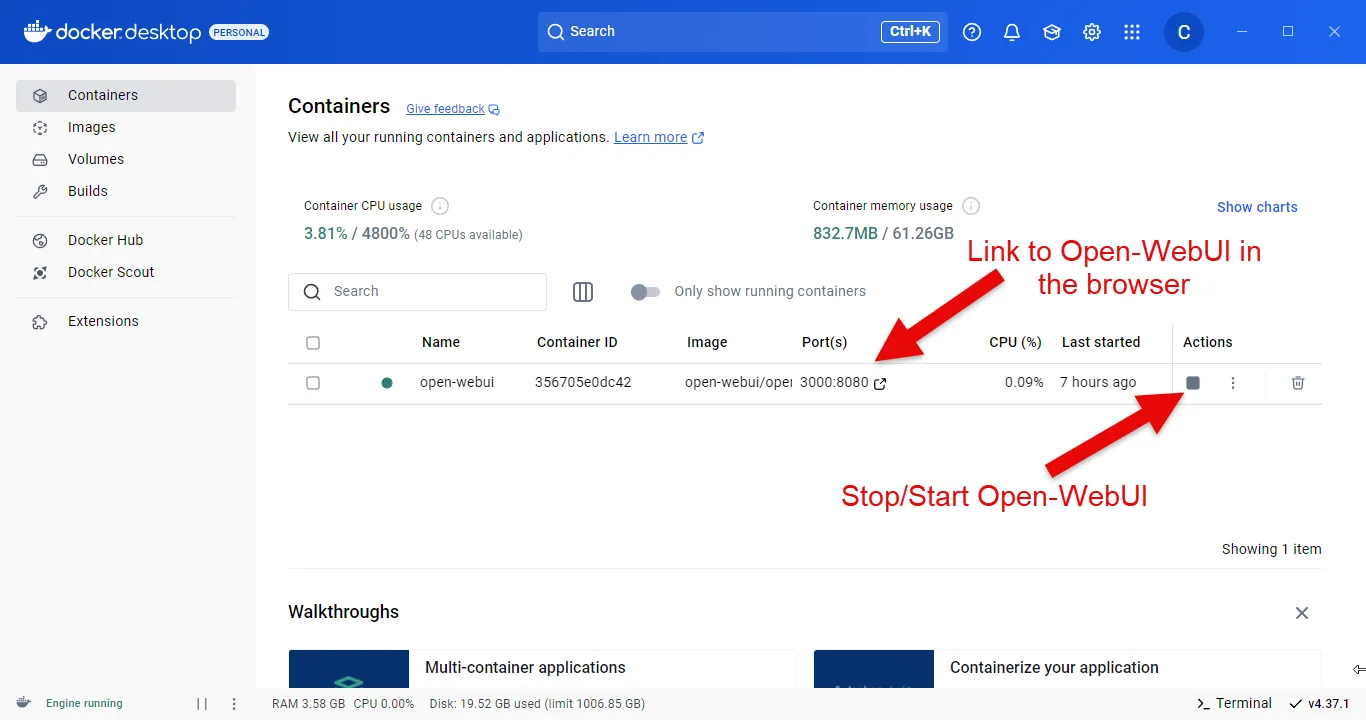
If you click the link under ‘Port(s)’ this will bring up Open-WebUI in a browser window.
When you first log in, Open-WebUI will prompt you to create an Admin account. Create your admin credentials and then you should be brought to a very ChatGPT-looking interface.
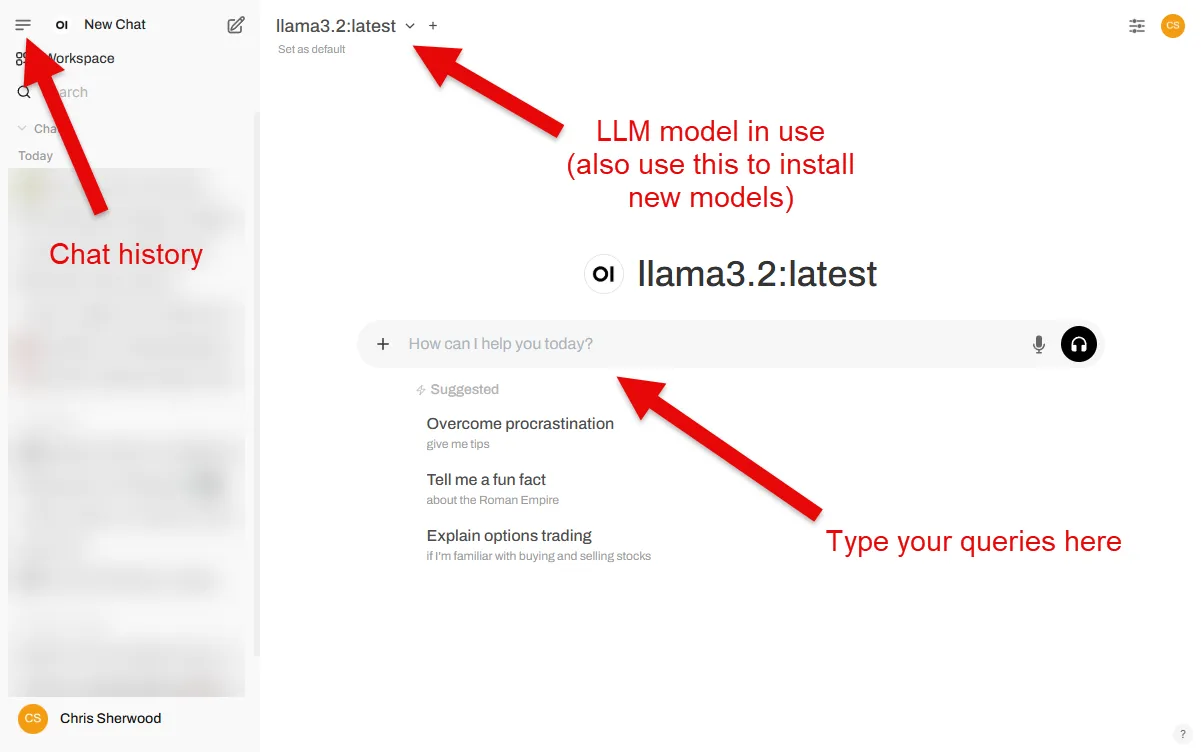
Success! The next thing we need to do is to start downloading some large language models.
First, let’s find an LLM to install. If you are unsure which to pick, Llama 3.2 is a good starter pick. Navigate back to Ollama.com and click on ‘Models.’
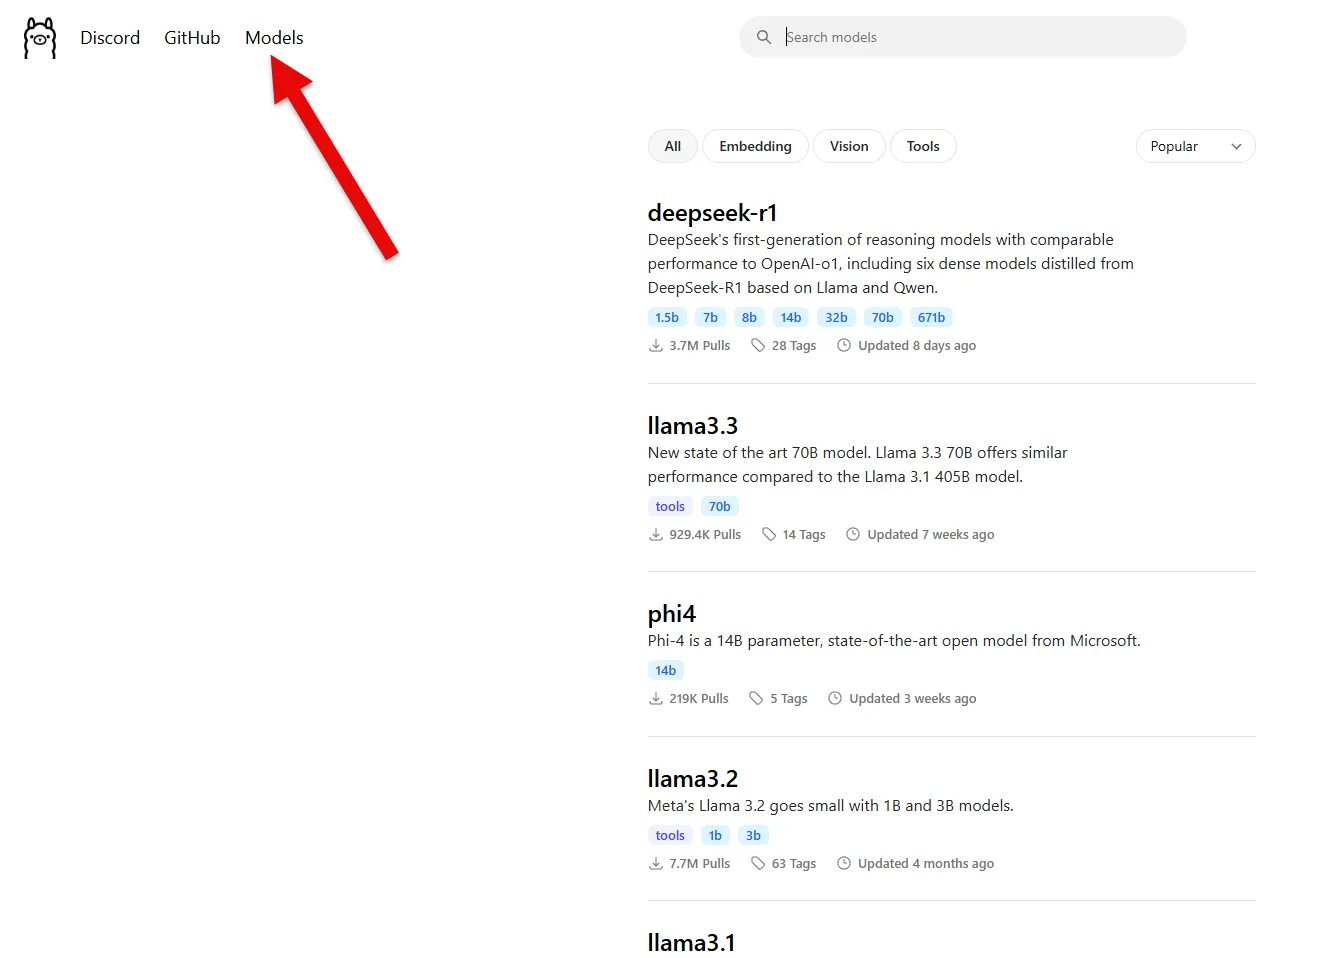
Models are sorted by popularity by default. The blue numbers underneath the various models are variations with more or less parameters (how much data the model was trained on). For Llama 3.2 we can see 1b and 3b. Click into that model and we can get even more detail.
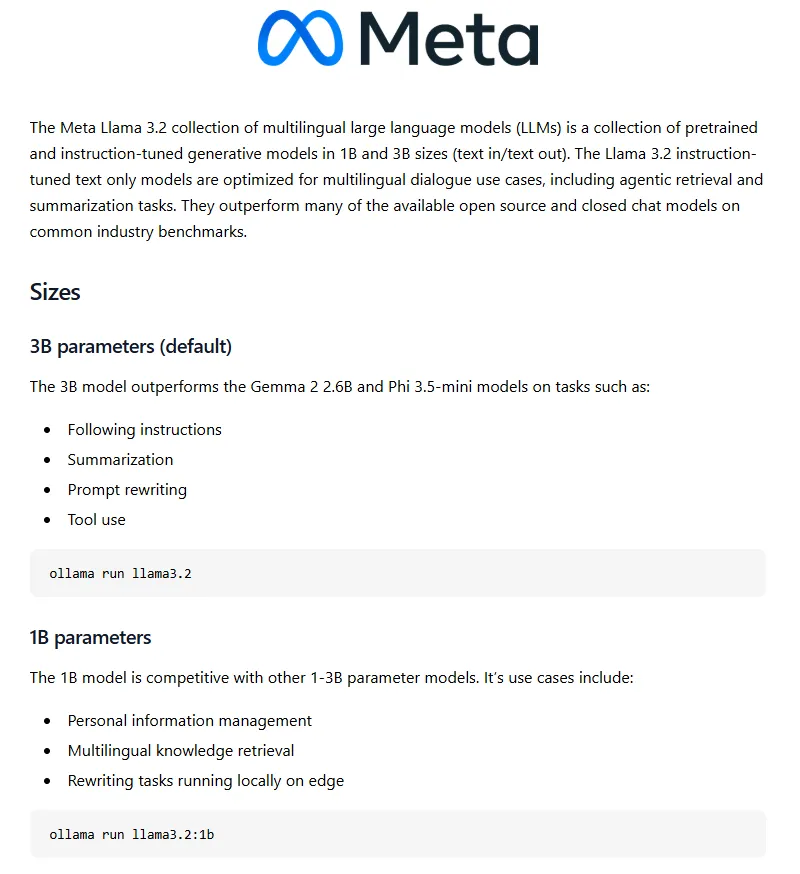
To install the models into Open-WebUI, we need to just grab the name. In this case, for the 3B (default) model, the name is simply ‘llama3.2’, but for the 1b variation, the name would be ‘llama3.2:1b’. For all of these models on Ollama.com, the model name is what comes after ‘ollama run.’
Copy the name you want and go back to Open-WebUI. Click the drop-down next to ‘Select a model’ and paste the name into the search bar. Since Open-WebUI doesn’t have that model installed, it gives you the option to pull the model from Ollama.com.
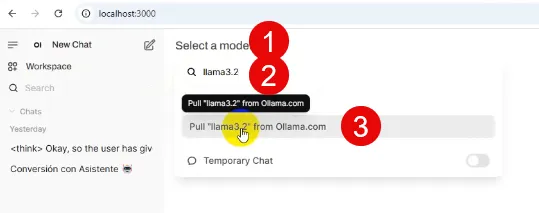
Models can be HUGE, so keep that in mind. The Deepseek 70B model is around 20GB to download. The smaller models are much more reasonable.
Once downloaded, you can start making queries against that model!
Keep playing around with various models and you’re sure to find ones that you like. You can even run 2 models side by side with the same query, but keep in mind that your processing power will be doubled when doing that.
If you enjoyed this tutorial, be sure to subscribe to Crosstalk Solutions on YouTube, and be sure to buy me a coffee!